Cloud & Platform Engineering004
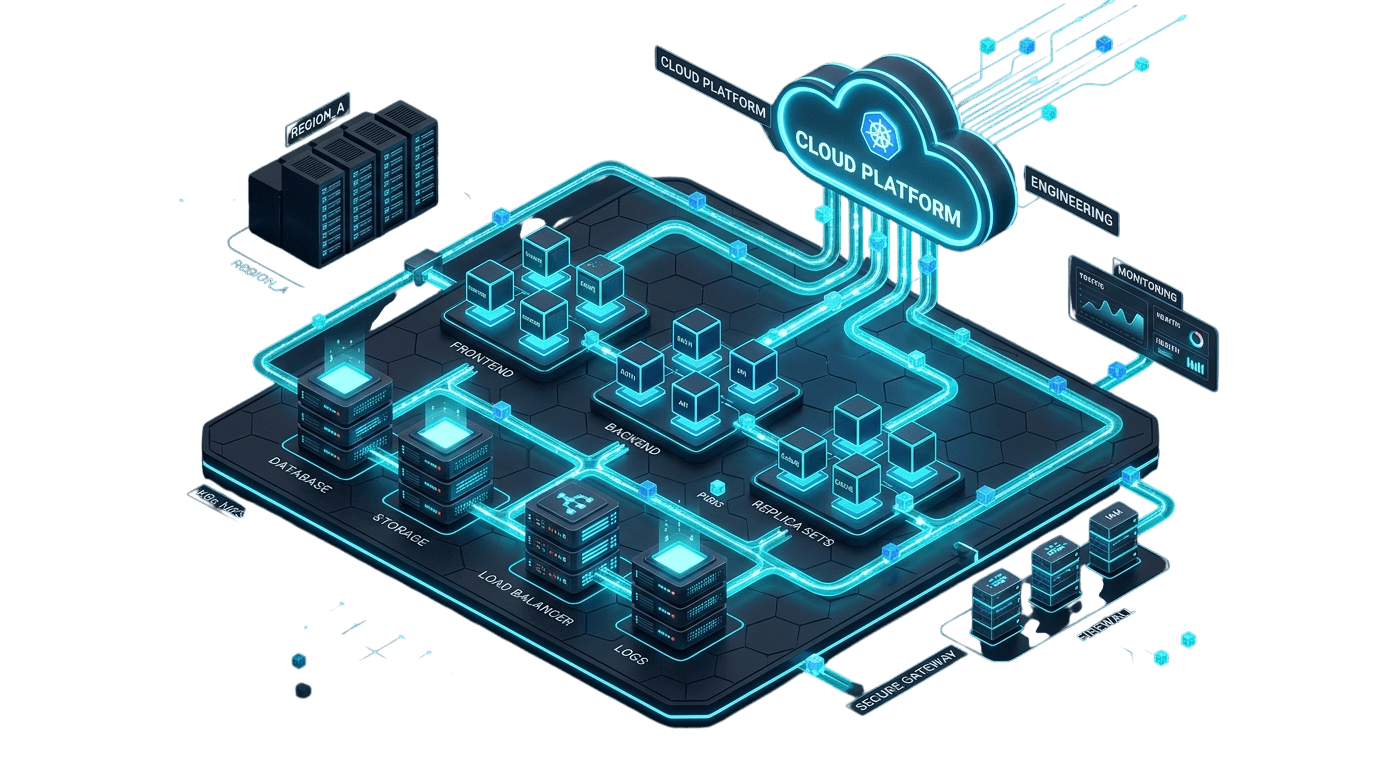
The infrastructure underneath — declared in code, reversible on deploy, and observable enough that an incident has an answer before it has a meeting.
- Terraform modules
- Kubernetes setup
- Observability stack
- Runbooks
Whether you're a rising startup or an established name, we engage this service the same way we engage every other one — a diagnostic before a proposal, and a shipped result measured against what we said it would do.
Service Overview
We build the infrastructure underneath the product — declared in code, reversible on deploy, and observable enough that an incident has an answer before it has a meeting. Nothing is a console click that only one engineer remembers making.
Environments, networking and secrets are designed as a reviewable diff from day one, so a new engineer can read the infrastructure the same way they read the application, and a rollback is a revert rather than a recovery project.
Client Goals
Make every environment reproducible from a reviewed diff, not from tribal knowledge of what one engineer clicked in a console.
Turn a bad deploy into a revert, not an incident, by keeping every change reversible by design.
Know what the platform spends and why, with utilisation visible before the invoice arrives, not after.
What Every Engagement Gets
Four commitments that hold the same way on every project, regardless of scope or budget.
Declared, Not Clicked
Every environment is defined in Terraform, reviewed the same way application code is.
Isolated Environments
Staging and production are genuinely separate, so a mistake in one can't reach the other.
Observability Built In
Logs, metrics and traces are wired in before the first workload ships, not added after the first outage.
Runbooks, Not Tribal Knowledge
Every service ships with a documented response for the failures it's known to have.
Tech Stack
The same toolkit behind every service, chosen for the discipline it enables.
Cloud-native compute, declarative orchestration, and global edge routing engineered for zero-downtime scalability.
Type-safe, memory-efficient languages and low-latency runtimes selected for high concurrency, fast startup, and long-term maintainability.
Relational, document, and distributed event streaming datastores tuned for strict ACID guarantees, high throughput, and replication.
Production-grade vector indexing, evaluation harnesses, and cognitive retrieval pipelines backing intelligent enterprise systems.
Automated CI/CD pipelines, end-to-end testing harnesses, and real-time observability telemetry guarding production releases.
Questions on cloud & platform work.
Both, depending on the engagement — we deliver infrastructure declared in code with observability and runbooks wired in, then transfer ownership to your team. Ongoing management is available where wanted, but the system is operable without us from day one.
Secrets live in a managed store with scoped, auditable access — never in repositories or environment files only one engineer knows about. Permissions follow least-privilege by default, and every grant is reviewable as part of the same diff as the infrastructure itself.
Reversible by design: changes land as reviewable diffs, run alongside the existing system, and cut over behind a flag you can pull. We rehearse the rollback before the migration, so reverting is a known procedure rather than an incident response.
Utilisation and spend are instrumented from the start — budgets, alerts and right-sizing recommendations are part of the platform, so cost is visible before the invoice arrives rather than explained after it does.
Technical briefingNot a sales desk